June 2017
Beginner to intermediate
349 pages
8h 34m
English
This chapter will briefly introduce our software stack. This stack is optimized for the process of doing agile data science.
By the end of this chapter, you’ll be collecting, storing, processing, publishing, and decorating data (Figure 2-1). Our stack enables one person to do all of this, to go “full stack.”
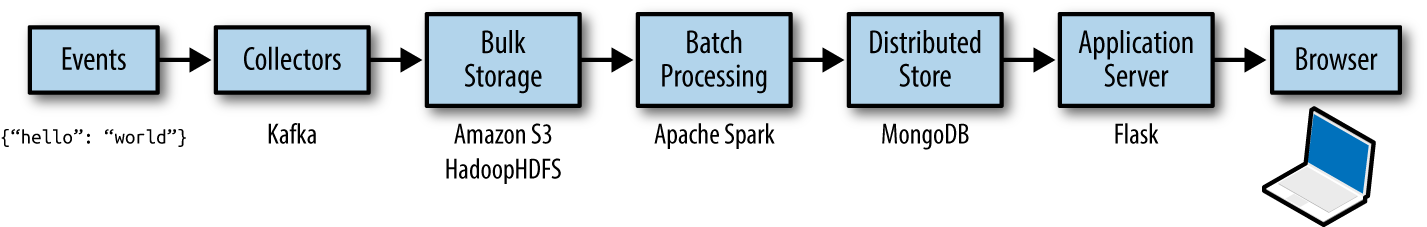
Full-stack skills are some of the most in demand for data scientists. We’ll cover a lot here, and quickly, but don’t worry: I will continue to demonstrate this software stack in Chapters 5 through 9. You need only understand the basics now; you will get more comfortable later.
We’ll begin with instructions for running the stack in local mode on your own machine. In the next chapter, you’ll learn how to scale this same stack in the cloud via Amazon Web Services. Let’s get started!
Code examples for this chapter are available at Agile_Data_Code_2/ch02. Clone the repository and follow along!
git clone https://github.com/rjurney/Agile_Data_Code_2.git
As NoSQL tools like Spark, Hadoop, and MongoDB, data science, and big data have developed, much focus has been placed on the plumbing of analytics applications. However, this is not a book about infrastructure. This book teaches you to build applications that use such infrastructure. Once our stack has been introduced, we will take this plumbing for granted ...
Read now
Unlock full access


 O’Reilly covers everything we've got, with content to help us build a world-class technology community, upgrade the capabilities and competencies of our teams, and improve overall team performance as well as their engagement.I wanted to learn C and C++, but it didn't click for me until I picked up an O'Reilly book. When I went on the O’Reilly platform, I was astonished to find all the books there, plus live events and sandboxes so you could play around with the technology.I’ve been on the O’Reilly platform for more than eight years. I use a couple of learning platforms, but I'm on O'Reilly more than anybody else. When you're there, you start learning. I'm never disappointed.I'm always learning. So when I got on to O'Reilly, I was like a kid in a candy store. There are playlists. There are answers. There's on-demand training. It's worth its weight in gold, in terms of what it allows me to do.