February 2019
Intermediate to advanced
386 pages
9h 54m
English
Cluster analysis (normally called just clustering) is an example of a task where we want to find out common features among large sets of samples. In this case, we always suppose the existence of a data generating process 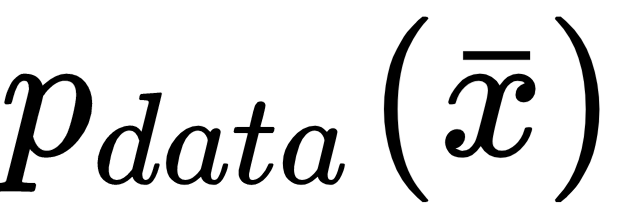 and we define the dataset X as:
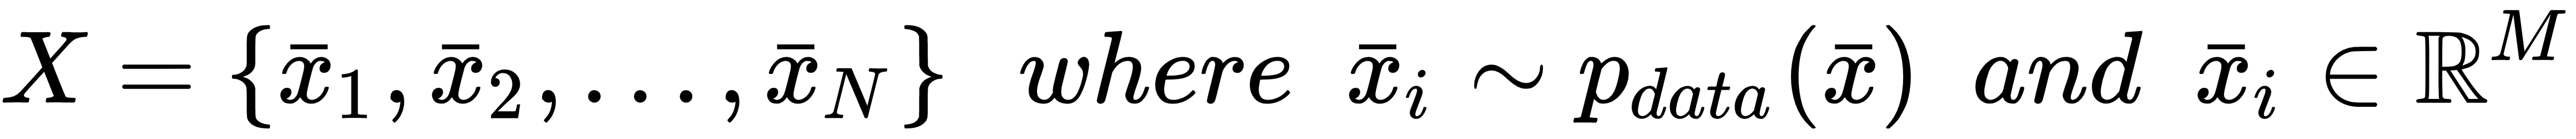
A clustering algorithm is based on the implicit assumption that samples can be grouped according to their similarities. In particular, given two vectors, a similarity function is defined as the reciprocal or inverse of a metric function. For example, if we are working in a Euclidean ...
Read now
Unlock full access


 O’Reilly covers everything we've got, with content to help us build a world-class technology community, upgrade the capabilities and competencies of our teams, and improve overall team performance as well as their engagement.I wanted to learn C and C++, but it didn't click for me until I picked up an O'Reilly book. When I went on the O’Reilly platform, I was astonished to find all the books there, plus live events and sandboxes so you could play around with the technology.I’ve been on the O’Reilly platform for more than eight years. I use a couple of learning platforms, but I'm on O'Reilly more than anybody else. When you're there, you start learning. I'm never disappointed.I'm always learning. So when I got on to O'Reilly, I was like a kid in a candy store. There are playlists. There are answers. There's on-demand training. It's worth its weight in gold, in terms of what it allows me to do.