December 2026
Beginner to intermediate
484 pages
12h 41m
English
The first step in training any large language model (LLM) is to prepare a massive, diverse, high-quality dataset called the pretraining dataset. Preparing this data is not a single-step process; it involves a complex pipeline of stages, including collection, cleaning, sampling, tokenization, and scheduling. This chapter walks through the practical stages involved in building such pretraining datasets, as illustrated in Figure 8-1.
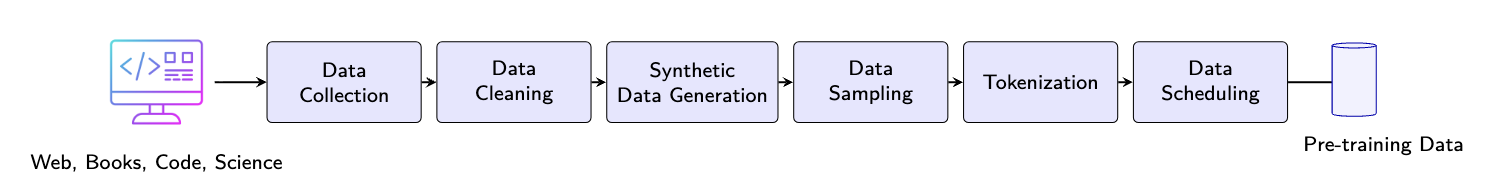
The first step in data preparation is to gather a large amount of data from various sources. LLMs are typically trained on multi-terabyte-scale corpora drawn from a mixture of general, domain-specific, and structured data. Common data sources includes:
Web and Crawl Data (e.g., Common Crawl): Massive, unstructured and loosely filtered web text from open domains. While rich in linguistic diversity and volume, this data requires extensive cleaning and filtering due to its noisiness and uneven quality.
Curated Reference Texts (e.g., Wikipedia, Books): High-quality, edited text from encyclopedias, literature, and educational materials. These sources provide grammatical correctness, factual grounding, and structured ...
Read now
Unlock full access


 O’Reilly covers everything we've got, with content to help us build a world-class technology community, upgrade the capabilities and competencies of our teams, and improve overall team performance as well as their engagement.I wanted to learn C and C++, but it didn't click for me until I picked up an O'Reilly book. When I went on the O’Reilly platform, I was astonished to find all the books there, plus live events and sandboxes so you could play around with the technology.I’ve been on the O’Reilly platform for more than eight years. I use a couple of learning platforms, but I'm on O'Reilly more than anybody else. When you're there, you start learning. I'm never disappointed.I'm always learning. So when I got on to O'Reilly, I was like a kid in a candy store. There are playlists. There are answers. There's on-demand training. It's worth its weight in gold, in terms of what it allows me to do.